# Beam Search
> Keep several candidate sentences alive at once, score each by how likely the whole thing is, and find out why the most likely sentence isn't always the best one.
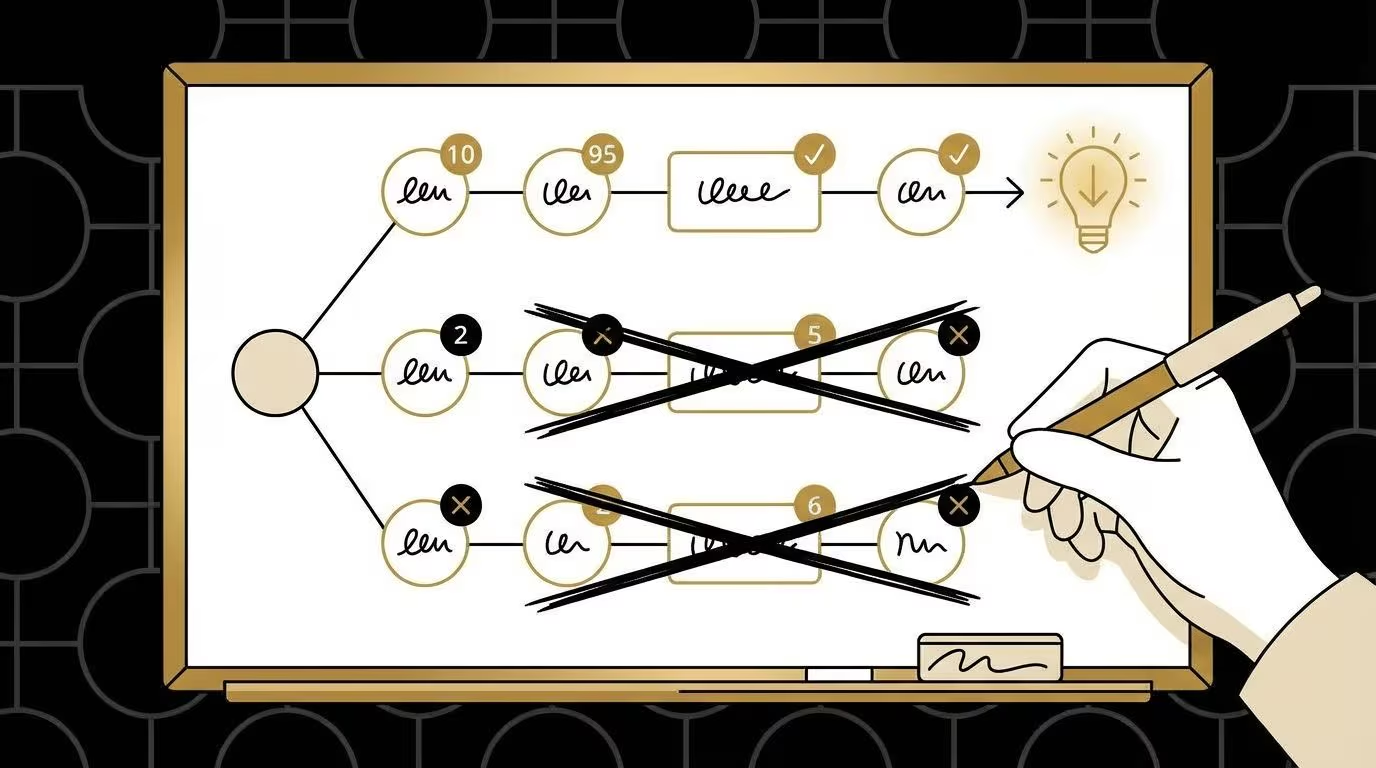
Every generation method so far picks one word, commits to it, and moves on. Beam search holds off: it keeps a handful of partial sentences going at once, scores each by how likely the whole sentence is, and only chooses once the sentences are finished. The examples use a short story about a magpie, written so that beam search and greedy generation disagree.
## You will need
- the model of _The magpie's nest_ below (or your own grid from
[Training](https://www.llmsunplugged.org/modules/training/))
- a sheet of paper or a whiteboard to track the beams, or strips of paper (one
per candidate sentence)
- a calculator, optional: the scores are fractions, and comparing them is easier
as decimals
## Your goal
Run beam search with a beam width of 2 from two starting points, and compare each result with greedy generation from the same start. Stretch goal: run it on a pre-trained booklet and try different beam widths.
## Key idea
Picking the most likely next word at every step doesn't always give the most
likely sentence, because a popular word can lead somewhere uncertain. Beam
search keeps the few best partial sentences at each step, so it can find a
sentence that starts with a less popular word. The most likely sentence still
isn't always a good one.
## The magpie's nest
The story:
> It is morning. The magpie sings. It flies to the tree. It sits in the nest.
> Here comes the cat. Down swoops the magpie! Off runs the cat. The magpie
> warbles. It flies back to the nest. Here comes the rain. It hides in the nest.
> The rain stops. The magpie sings. It flies to the tree. The magpie eats a
> worm. The sun sets. It sleeps in the nest. It is morning. The magpie sings.
Here is its bigram model. Each row gives a word, how many times something
followed it, and what followed. A word's **share** of a row is its count divided
by the row total: after `the`, `magpie` has a share of 6/17.
| word | total | followed by |
| --------- | ----- | ---------------------------------------------------------- |
| `It` | 8 | `flies` 3, `is` 2, `hides` 1, `sits` 1, `sleeps` 1 |
| `is` | 2 | `morning` 2 |
| `morning` | 2 | `.` 2 |
| `.` | 17 | `It` 7, `the` 7, `Here` 2, `Down` 1 |
| `the` | 17 | `magpie` 6, `nest` 4, `cat` 2, `rain` 2, `tree` 2, `sun` 1 |
| `magpie` | 6 | `sings` 3, `!` 1, `eats` 1, `warbles` 1 |
| `sings` | 3 | `.` 3 |
| `flies` | 3 | `to` 2, `back` 1 |
| `to` | 3 | `the` 3 |
| `tree` | 2 | `.` 2 |
| `sits` | 1 | `in` 1 |
| `in` | 3 | `the` 3 |
| `nest` | 4 | `.` 4 |
| `Here` | 2 | `comes` 2 |
| `comes` | 2 | `the` 2 |
| `cat` | 2 | `.` 2 |
| `Down` | 1 | `swoops` 1 |
| `swoops` | 1 | `the` 1 |
| `!` | 1 | `Off` 1 |
| `Off` | 1 | `runs` 1 |
| `runs` | 1 | `the` 1 |
| `warbles` | 1 | `.` 1 |
| `back` | 1 | `to` 1 |
| `rain` | 2 | `.` 1, `stops` 1 |
| `hides` | 1 | `in` 1 |
| `stops` | 1 | `.` 1 |
| `eats` | 1 | `a` 1 |
| `a` | 1 | `worm` 1 |
| `worm` | 1 | `.` 1 |
| `sun` | 1 | `sets` 1 |
| `sets` | 1 | `.` 1 |
| `sleeps` | 1 | `in` 1 |
`.` and `!` are words too. `The` at the start of a sentence is counted as `the`,
since it's the same word; `It` keeps its capital because the story never uses
it mid-sentence.
## Algorithm
A **beam** is one partial sentence plus its score. The score is how likely that
whole sentence is: multiply together the share of every word you've added. A
sentence is **finished** when it reaches `.` or `!`.
1. **Start:** one beam, holding your starting words, with a score of 1.
2. **Expand:** for every unfinished beam, write out each word that can follow
its last word, with the new score (the beam's score times that word's share).
Finished beams carry over unchanged.
3. **Prune:** keep the _k_ highest-scoring candidates, where _k_ is the beam
width. If there's a tie for the last place, keep all the tied ones.
4. **Repeat** from step 2 until every beam you kept is finished.
5. **Choose** the finished sentence with the highest score.
A beam width of 1 is greedy generation: take the most likely word every time,
the "cold" setting in [Sampling](https://www.llmsunplugged.org/modules/sampling/).
## Worked example: "It sleeps in the..."
Start from `It sleeps in the`, with a beam width of 2. Those starting words
are given, so the score starts at 1.
**Expand `the`.** Six candidates:
| candidate | score |
| ------------ | ----- |
| `the magpie` | 6/17 |
| `the nest` | 4/17 |
| `the cat` | 2/17 |
| `the rain` | 2/17 |
| `the tree` | 2/17 |
| `the sun` | 1/17 |
**Prune.** Keep `the magpie` and `the nest`; the other four are cut.
**Expand each beam.** After `magpie` the story goes four ways, and `sings` has
half of the row. After `nest` there is only ever `.`:
| candidate | score |
| -------------------- | ----------------- |
| `the nest .` | 4/17 × 4/4 = 4/17 |
| `the magpie sings` | 6/17 × 3/6 = 3/17 |
| `the magpie !` | 6/17 × 1/6 = 1/17 |
| `the magpie eats` | 6/17 × 1/6 = 1/17 |
| `the magpie warbles` | 6/17 × 1/6 = 1/17 |
**Prune.** Keep `the nest .` and `the magpie sings`. One more step finishes
`the magpie sings .` at 3/17 (`sings` is always followed by `.`), and every
beam is finished.
The winner is **"It sleeps in the nest."**, with a score of 4/17.
Greedy generation (beam width 1) takes `magpie` at the first step, because it's
the most popular word after `the`, and ends on "It sleeps in the magpie sings."
with a score of 3/17. Keeping `nest` for one more step was enough, because `nest` is
always followed by `.`, so its score held while the magpie's halved.
## Your turn: "It..."
Start from `It` with a beam width of 2 and run the algorithm until every beam is
finished. Then run greedy from `It` and compare.
Greedy writes "It flies to the magpie sings." (3/68). Beam search picks **"It is
morning."** (1/4), the shortest sentence the model can make from `It`. On the
way it prunes "It flies to the tree.", a line straight out of the story: at the
moment it's a candidate, `It flies to the magpie` is ahead of it, and the cut is
made before anyone sees how each sentence ends.
"It is morning." wins because it's short. Every word you add multiplies the
score by a share of 1 or less, so a longer sentence can only lose ground.
## Tracking beams in practice
- **Whiteboard:** one line per candidate, with its score at the end. Cross out
the pruned ones at each step, so the board shows the whole search afterwards.
- **Paper strips:** write each candidate on a strip with its score. At each
step, line the strips up by score and set aside everything below the cut.
- **People:** with a beam width of 2 or 3, one person holds each beam and reads
out its candidates; the group decides which survive.
## Going further
Start from `Here comes the`. Beam search runs exactly as in the worked example
and finds the most likely sentence: "Here comes the nest." Is it a good
sentence?
Then run beam search on a [pre-trained booklet](https://www.llmsunplugged.org/modules/pretrained-generation/).
A word's share is the fraction of the die faces that land on it: count the faces
in its range and divide by the faces on the die. Try beam widths of 1, 2 and 3
from the same starting word. Does a wider beam ever change the answer? Does it
ever make it worse?
Allow plenty of time, and don't expect a clear winner. A booklet's rows are long
and each lookup is slow, so a whole session may only get a few words into one
sentence, and the best candidate may score just a little above the rest. For the
clear case, where greedy and beam search disagree, use the magpie's nest.
## Instructor notes
### Discussion questions
- why did greedy miss "It sleeps in the nest."? At which step did it go wrong?
- "Here comes the nest." is the most likely sentence from `Here comes the`. Is
it the best one? What does the model not know that you do?
- why does "It is morning." beat every longer sentence? How could you change
the scoring so that long sentences get a fair go?
- "It flies to the tree." got pruned even though it's a line from the story.
Would a wider beam have saved it? What does a wider beam cost?
- when would you want the single most likely output (translating a sentence,
transcribing speech), and when would you rather roll the dice?
### Troubleshooting
- **"There's a tie for the last place."** Keep all the tied candidates, as in
top-k in [Sampling](https://www.llmsunplugged.org/modules/sampling/). This can make the beam wider than _k_
for a step or two; it narrows again at the next cut. The magpie's nest has no
ties at any cut in the examples on this page, but your own grid might.
- **"One beam finished early."** It stays in the running with the same score,
and takes up one of the _k_ places. It doesn't expand any further.
- **"The fractions are getting ugly."** Use a calculator and decimals to two
places, or keep every score over a common denominator, as the worked example
does with seventeenths.
- **"Our model has no ties and no dead ends, so nothing interesting happens."**
Beam search only differs from greedy where a popular word leads somewhere
uncertain. Look for a row whose favourite is followed by a split row, next to
a less popular word that is followed by a sure thing. In the magpie's nest
that's `magpie` (split four ways) next to `nest` (always `.`).
### Connection to current LLMs
Beam search is a decoding strategy: a rule for turning a model's next-word chances into text, separate from the model itself. Real implementations follow the same steps as your whiteboard, at larger scale. The model scores every token in its vocabulary at each step, so a beam of width 5 expands five beams into hundreds of thousands of candidates and keeps five. And implementations add the logarithms of the shares, because multiplying hundreds of small fractions underflows decimal precision.
Beam search is the standard choice where there's roughly one right answer:
machine translation and speech recognition, where you want the most likely
transcription. It's usually run with a length penalty, for the reason "It is
morning." won: the score is divided by something that grows with the sentence
length, so longer sentences aren't punished just for being longer.
Chatbots like Claude or ChatGPT mostly don't use it. They sample, with the temperature and truncation controls from [Sampling](https://www.llmsunplugged.org/modules/sampling/). When researchers ran beam search on open-ended text, they found [the most likely text is bland and repetitive, and nothing like what people write](https://arxiv.org/abs/1904.09751).
Source: \
Licence: [CC-BY-SA-4.0](https://creativecommons.org/licenses/by-sa/4.0/)\
Cite as: Swift, B. (2026). _LLMs Unplugged: Understand how AI language models work by building one yourself._ https://doi.org/10.5281/zenodo.17403824